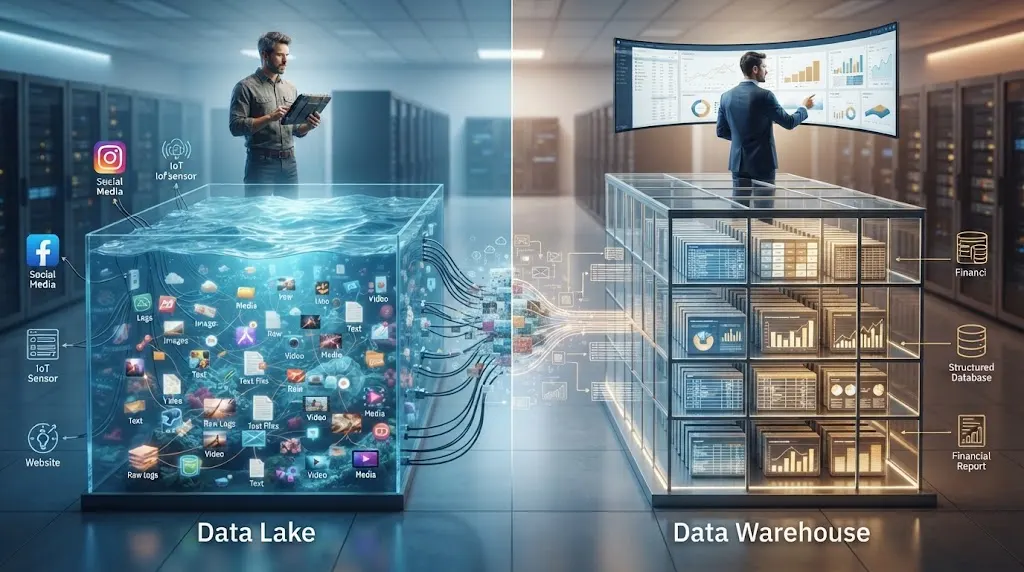

Businesses collect more data than ever before, but storing that information effectively is only part of the challenge. Organizations also need systems that make data accessible, organized, secure, and useful for analytics. Two of the most common approaches are data lakes and data warehouses, each designed for different types of information and analytical requirements.
Understanding the difference between a data lake and a data warehouse can help businesses choose the right architecture for reporting, machine learning, business intelligence, and long-term data management. Although both systems store large amounts of information, they differ significantly in structure, processing, cost, users, governance, and the way data is prepared before analysis.
What Is a Data Lake?
A data lake is a centralized storage environment designed to hold large volumes of raw data in its original format. It can store structured information from databases alongside semi-structured and unstructured data such as JSON files, images, videos, logs, documents, and sensor information. Organizations can collect information first and decide how to analyze it later.
Unlike traditional systems that require information to be cleaned and organized before storage, data lakes usually follow a schema-on-read approach. This means the structure is applied when the information is accessed for analysis. The flexibility allows data scientists and engineers to experiment with datasets without knowing every future analytical requirement in advance.
Data lakes are commonly associated with big data analytics, artificial intelligence, machine learning, and exploratory analysis. They are particularly useful when organizations generate enormous quantities of diverse information from applications, IoT devices, websites, transactions, and cloud platforms. However, effective metadata management and governance are essential to prevent the environment from becoming difficult to navigate.
What Is a Data Warehouse?
A data warehouse is a centralized system designed primarily for storing structured, processed, and organized business information. Data normally comes from multiple operational systems, including customer relationship management software, financial databases, sales platforms, and enterprise applications. It is cleaned and transformed before being stored so users can perform reliable reporting and analysis.
The architecture typically follows a schema-on-write approach, meaning the structure and rules are defined before information enters the warehouse. This creates consistency across datasets and makes business metrics easier to understand. If you want a deeper introduction, this simple guide to a data warehouse explains how the technology organizes information for analytics and reporting.
Data warehouses are widely used by business analysts, managers, finance teams, marketers, and executives who need consistent reporting. They work particularly well for dashboards, historical comparisons, performance monitoring, and business intelligence. Because information has already been prepared, users can usually query warehouse data quickly without performing extensive cleaning every time they create a report.
Data Lake vs Data Warehouse: The Main Difference
The biggest difference between a data lake and a data warehouse is how information is stored and prepared. Data lakes generally keep information in its raw form, while data warehouses contain structured and processed information. A lake prioritizes flexibility, whereas a warehouse prioritizes consistency, reliability, and straightforward access for business reporting.
Another important distinction is how each system handles future analytical requirements. A data lake allows organizations to store information even when they do not yet know exactly how it will be used. A warehouse requires businesses to define much of the data model beforehand, making it especially effective when reporting needs and business metrics are already understood.
The users are also different in many organizations. Data scientists and engineers often prefer lakes because they need access to detailed raw information for experimentation and advanced analytics. Business analysts and executives generally prefer warehouses because they provide cleaner datasets and standardized definitions that can be used directly in dashboards, reports, and decision-making processes.
Differences in Data Types and Storage
Data lakes are capable of storing almost any type of information without requiring a predefined structure. Structured database records can exist alongside social media data, application logs, video files, audio, PDFs, clickstream information, and machine-generated records. This flexibility makes lakes attractive to organizations working with large-scale or rapidly changing data sources.
Data warehouses primarily focus on structured or highly organized information. Before data enters the warehouse, it is usually transformed into consistent tables with defined relationships, columns, data types, and business rules. This approach makes analytical queries more predictable because users know how the information is organized and what individual fields represent.
The storage choice therefore depends heavily on what kind of data an organization generates. Companies relying mainly on structured sales, customer, inventory, and financial information may find a warehouse sufficient. Organizations collecting large volumes of logs, multimedia, sensor information, and experimental datasets may benefit more from the flexibility provided by a modern data lake.
Schema-on-Read vs Schema-on-Write
Data lakes commonly use schema-on-read, which means information does not need to fit a rigid model when it is first stored. Analysts can determine how to structure the dataset when they access it for a particular project. This provides flexibility because the same underlying information can potentially be interpreted differently depending on the analytical objective.
Data warehouses usually rely on schema-on-write, where information must follow predefined structures before entering the system. Data engineers often clean, standardize, validate, and transform records during an ETL or ELT workflow. This additional preparation makes downstream reporting more consistent because definitions and relationships are established before business users begin working with the information.
Neither method is universally better because they solve different problems. Schema-on-read is valuable for discovery, experimentation, and rapidly evolving datasets, while schema-on-write works well when accuracy and consistency are critical. Many organizations now combine both methods, using flexible storage for raw data and structured layers for trusted reporting and business intelligence.
Data Processing and Transformation
Processing is another major difference when comparing a data lake vs data warehouse. In a lake, data can often be stored immediately after collection with limited transformation. Engineers may process it later using distributed computing tools, notebooks, machine learning frameworks, or specialized analytics platforms depending on the requirements of a particular project.
Warehouse workflows traditionally involve transforming information before or during loading. Teams may remove duplicates, standardize formats, validate records, calculate business metrics, and combine information from several systems. These preparation steps help create trusted datasets that are easier for analysts to query without repeatedly fixing quality problems before creating each dashboard or report.
Modern cloud architectures have made the distinction less rigid than it once was. Cloud warehouses can increasingly handle semi-structured information, while advanced lake platforms can provide SQL analytics and structured tables. Even so, the underlying philosophy remains different: lakes emphasize flexible storage, while warehouses emphasize curated information optimized for consistent analytical use.
Performance and Query Speed
Data warehouses are generally designed for fast analytical queries across structured datasets. Indexing, columnar storage, query optimization, caching, and predefined schemas help users retrieve aggregated business information efficiently. This performance is valuable when employees regularly access dashboards showing metrics such as revenue, customer acquisition, product performance, operating costs, or monthly sales.
Data lakes may require more processing before users can query information efficiently because raw files can vary significantly in structure and quality. Performance depends on file formats, partitioning, metadata, computing engines, and how well the environment has been organized. Poorly managed storage can make analysis slower and significantly increase the amount of computing required.
Technology improvements have narrowed this performance gap considerably. Formats such as Parquet and modern table technologies can make lake-based analytics substantially faster than traditional raw-file approaches. However, organizations still need careful architecture and optimization to deliver the predictable performance business users often expect from established warehouse environments and business intelligence applications.
Users and Common Use Cases
Business analysts are among the most common users of data warehouses because they regularly need consistent information for dashboards, KPIs, forecasting, and operational reports. Finance teams might analyze quarterly revenue, while marketers may evaluate campaign conversions and sales leaders monitor pipeline performance. These activities rely on structured information with clearly defined business logic.
Data lakes tend to serve data scientists, machine learning engineers, and technical analysts who need access to detailed or unprocessed information. They might use website logs to build recommendation systems, analyze sensor data to predict equipment failure, or train machine learning models with millions of records. Flexibility is more important than immediate reporting simplicity in these scenarios.
Large organizations often use both systems because their departments have different analytical needs. A data lake might preserve detailed source information for advanced analytics, while selected datasets are transformed and loaded into a warehouse for reporting. This combined architecture allows technical teams to experiment without sacrificing the reliability business users require for everyday decisions.
Cost and Scalability Differences
Data lakes have traditionally offered lower-cost storage because they can use scalable object storage to hold enormous quantities of information. Businesses can retain historical and raw datasets without immediately investing in extensive processing. This approach is useful when organizations want to preserve information that could become valuable later but does not currently require frequent analysis.
Data warehouses can involve higher costs because structured data preparation and analytical computing require additional resources. Cloud warehouses have improved scalability by separating storage and processing, allowing companies to increase computing capacity when necessary. Costs can still rise quickly when many users run complex queries or when workloads are not carefully monitored and optimized.
Price should never be evaluated based on storage costs alone. Engineering time, governance, security, data quality, computing requirements, maintenance, and employee training can all influence the total cost of ownership. A cheaper storage system may ultimately become expensive if teams spend substantial time finding, cleaning, and preparing information before every analytical project.
Governance, Security, and Data Quality
Data warehouses traditionally provide strong governance because information passes through structured preparation processes before becoming available for analysis. Organizations can establish standardized definitions, access permissions, quality checks, and reporting rules. This controlled environment reduces the risk of different departments calculating the same business metric in completely different ways.
Data lakes can be more challenging to govern because they often contain enormous quantities of raw information from many sources. Without good metadata, cataloging, ownership, and access controls, users may struggle to determine which datasets are trustworthy. In extreme cases, an unmanaged lake can become a confusing collection of poorly documented information sometimes described as a data swamp.
Modern data platforms now offer stronger governance capabilities for lake environments, including catalogs, lineage tracking, role-based permissions, and quality monitoring. Nevertheless, technology alone does not solve governance problems. Organizations need clear ownership, retention policies, naming standards, documentation, security procedures, and processes for determining which datasets should be treated as reliable business information.
When Should You Choose a Data Lake?
A data lake may be the better option when an organization collects large quantities of diverse information and cannot predict all future use cases. Businesses developing artificial intelligence, recommendation engines, predictive models, or IoT analytics often need access to detailed raw records. Keeping the original information gives technical teams greater freedom to experiment.
Lakes can also be useful when data arrives rapidly from many different systems. Instead of designing a separate structured model for every new source, engineers can ingest information quickly and organize it later. This approach supports innovation, but companies still need metadata management and governance so employees can discover and understand the available datasets.
Choosing a data lake does not mean every employee should query raw information directly. Many organizations create curated layers that prepare selected datasets for specific analytical purposes. This allows the business to retain flexible raw storage while also providing cleaner information for downstream applications, reporting systems, and teams that need predictable analytical results.
When Should You Choose a Data Warehouse?
A data warehouse is usually appropriate when the primary goal is business intelligence, standardized reporting, and reliable performance metrics. Organizations that need consistent answers to questions about revenue, profit, customers, inventory, operations, or marketing performance benefit from structured datasets. Users can spend more time analyzing results instead of repeatedly preparing raw information.
Warehouses are particularly useful when executives and nontechnical employees need self-service dashboards. Because data has already been cleaned and modeled, users can explore metrics with familiar reporting software without understanding complicated engineering workflows. Consistent definitions also reduce disagreements about important KPIs, such as customer lifetime value, gross margin, or monthly recurring revenue.
However, a warehouse may be less suitable as the only storage environment when organizations generate significant amounts of unstructured or experimental data. Forcing every dataset into predefined relational models can reduce flexibility. Businesses with both traditional reporting and advanced analytics requirements often benefit from combining a warehouse with a more flexible lake-based storage layer.
What Is a Data Lakehouse?
A data lakehouse is a newer architectural approach that attempts to combine the flexibility of data lakes with the management and performance features associated with data warehouses. It allows organizations to maintain large-scale storage while introducing structured tables, transactions, governance, and optimized analytical access. The goal is to reduce unnecessary separation between different data systems.
With a lakehouse architecture, data scientists can work with detailed information while analysts access structured versions through SQL and business intelligence tools. Shared storage can reduce the need to copy information between separate environments. This can simplify architecture, although successful implementation still requires careful data modeling, governance, security, and performance management.
A lakehouse does not automatically eliminate the need for warehouses or traditional lakes in every organization. Existing systems, skills, workloads, regulatory requirements, and reporting applications all influence architectural decisions. Businesses should evaluate their real analytical needs before replacing proven systems simply because a newer technology or architecture has become popular.
Conclusion
The data lake vs data warehouse comparison is ultimately about how an organization wants to store, prepare, and use information. Data lakes provide flexibility for raw, structured, semi-structured, and unstructured datasets. Data warehouses focus on curated and organized information that supports predictable business intelligence, reporting, and analytical performance.
Data lakes are especially useful for machine learning, exploratory analytics, big data, and rapidly changing information sources. Warehouses are usually more suitable for dashboards, historical reporting, financial analysis, and standardized KPIs. Neither architecture is universally superior because each one addresses different technical requirements, business users, and analytical goals.
Many modern organizations use both approaches or adopt lakehouse technologies that combine elements of each. The right decision should depend on your data types, users, governance requirements, analytical workloads, budget, and future plans. A well-designed architecture makes information easier to trust, access, analyze, and ultimately turn into useful business insights.
FAQs
What is the main difference between a data lake and a data warehouse?
A data lake typically stores raw data in many formats, while a data warehouse stores structured and processed information. Lakes prioritize flexibility, whereas warehouses prioritize consistency and business reporting.
Is a data lake cheaper than a data warehouse?
Data lake storage is often relatively inexpensive, especially for large volumes of raw information. However, total costs also depend on computing, engineering, governance, security, maintenance, and data-processing requirements.
Can a company use both a data lake and a data warehouse?
Yes. Many businesses store detailed raw information in a data lake and move curated datasets into a warehouse for reporting. This approach supports both advanced analytics and traditional business intelligence requirements.
Is a data warehouse better for business intelligence?
Data warehouses are commonly suited to business intelligence because information is structured, cleaned, and optimized for analytical queries. This makes them useful for dashboards, recurring reports, KPIs, and decision-making across business teams.
What is the difference between a data lake and a data lakehouse?
A data lake mainly provides flexible storage for diverse information, while a lakehouse adds warehouse-like features such as structured tables, transactions, governance, and improved query performance to lake-based storage.